
At 2 a.m., a mobile lead ships an over-the-air fix after a Capacitor regression breaks checkout on Android. By morning, support tickets are piling up, but nobody can confirm which installed versions received the JavaScript bundle, which cohorts executed the broken path, or whether a silent retry is hiding the failure. The CTO wants adoption data, the privacy lead wants a DPIA, and the on-call engineer wants to know whether rollback reached users.
That situation exposes the purpose of app behavior tracking. It isn’t just a growth dashboard or a privacy debate. For teams shipping Capacitor and Electron applications into fragmented device fleets, tracking is an engineering system for reconstructing behavior, validating releases, detecting regressions, and proving that collection remains controlled. The implementation details matter, from event schemas and durable queues to sampling rules, regional storage, and incident recovery.
Table of Contents
- Why App Behavior Tracking Matters in 2026
- What App Behavior Tracking Actually Means
- Comparing the Main Tracking Approaches
- Architecture and Event Schemas for Mobile and Desktop Apps
- Sampling and Performance Trade-Offs
- Privacy and Compliance as a Design Constraint
- Metrics, Dashboards, and Alerting That Actually Help
- Best Practices and an Incident Recovery Checklist
Why App Behavior Tracking Matters in 2026
A crash report might tell you that checkout failed. It usually won’t tell you whether the failure came from a stale web bundle, a native plugin boundary, a particular renderer process, or a retry loop that eventually succeeded. Without behavioral context, the team has to correlate support tickets, release logs, and partial server evidence by hand.
The first useful question after an OTA release is often simple: did the intended users receive and execute the update? Answering it requires more than a version string. You need the installed native shell, active JavaScript bundle, update channel, launch result, device platform, and meaningful business events around the affected flow. A successful download doesn’t prove a successful activation, and an activated bundle doesn’t prove that a user reached the repaired screen.
Practical rule: Track release state and user outcome as separate event families. Combining them into one “update success” event makes rollback analysis unreliable.
Capacitor app observability fits into production practice. A useful pipeline connects release operations with runtime behavior, so an engineer can move from “checkout reports increased” to a bounded query involving app version, bundle version, platform, channel, and event sequence.
The privacy constraint is inseparable from that design. Apple’s App Tracking Transparency framework, introduced in 2021, changed cross-app tracking from implicit opt-out to explicit opt-in. A 2025 analysis found that the share of Apple users trackable by advertisers in the United States fell from 72.63% before ATT to 17.9% afterward, a decline of 54.73 percentage points (9to5Mac’s analysis of the ATT update). That change doesn’t eliminate first-party product telemetry, but it does make identifier strategy, consent state, and attribution boundaries architectural decisions.
What App Behavior Tracking Actually Means
Treat app behavior tracking like a flight data recorder for software. It captures what the application did, in which order, and under what conditions, so you can reconstruct a session after the fact instead of guessing from a crash stack.
The label covers several systems that answer different questions.
Event tracking records discrete facts
An event is a named, structured occurrence such as checkout_started, payment_submitted, screen_viewed, or bundle_activated. A well-designed event carries context, including the app version, platform, session identifier, and relevant feature state. It should describe something that happened, not reproduce an entire object from memory.
Event tracking is excellent for funnels, release verification, and operational queries. It misses visual ambiguity. If a user taps a control that looks enabled but has no handler, an event may show the preceding screen view without explaining the interface problem.
Session replay preserves interaction context
Session replay captures a visual and interaction stream, often through DOM or view-tree snapshots, gestures, and navigation state. It can reveal clipped text, confusing focus behavior, or repeated taps that structured events never represent.
The trade-off is exposure. Replay data can contain more sensitive context than a carefully designed event, especially when free text, account screens, or payment flows aren’t masked correctly. It also depends on reliable capture and rendering, so it shouldn’t be the only record of a business-critical action.
Analytics turns events into decisions
Analytics systems aggregate events into funnels, cohorts, paths, and retention views. They answer questions such as where users abandon a workflow or whether a release changes feature adoption.
Analytics is downstream interpretation, not instrumentation. If event names drift between mobile and desktop, the dashboard may still load while comparing incompatible definitions.
Error and telemetry tracking explains reliability
Error tracking captures crashes, exceptions, logs, network failures, and performance traces. It answers whether the application survived and how long operations took.
Telemetry is often too blunt to explain intent. A slow API span matters more when it can be connected to a user action such as “attempted checkout,” but that connection should use stable correlation fields rather than copying personal data into every log line.
Comparing the Main Tracking Approaches
The right choice depends on the question, the acceptable exposure, and how much operational complexity the team can own. Cost varies widely by vendor, retention policy, payload size, and query model, so a fixed price per million events would be misleading without a defined infrastructure and vendor context.
Tracking approaches at a glance
| Approach | Data Shape | Latency | Cost (per 1M) | Privacy Exposure | Best For |
|---|---|---|---|---|---|
| Event tracking | Structured records with named actions and context | Usually near real time to delayed, depending on batching | Variable, driven by payload size, ingestion, storage, and query volume | Moderate if identifiers or properties are excessive | Funnels, release adoption, feature usage, workflow verification |
| Session replay | Visual frames, snapshots, gestures, and interaction metadata | Often delayed by upload and processing | Usually higher operational and storage burden because payloads are richer | High, especially when text, forms, or account views aren’t masked | Reproducing UI friction and ambiguous interaction failures |
| Analytics | Aggregated funnels, cohorts, paths, and retention outputs | Depends on warehouse or vendor processing | Query and storage costs can grow when raw events are retained alongside aggregates | Inherits exposure from source events and identity joins | Product decisions and longitudinal behavior analysis |
| Error and telemetry tracking | Stack traces, logs, spans, timings, and device state | Commonly fast for incidents, subject to queue and network availability | Often lower per record, but high-volume logs can become expensive | Moderate, especially when logs include request data or user input | Crash diagnosis, performance analysis, and pipeline health |
The most common mistake is enabling all four systems with overlapping schemas and no ownership. Product analytics calls an action purchase_completed, the error pipeline emits payment_success, and the replay tool infers completion from a screen transition. The dashboards disagree, engineers spend time reconciling definitions, and nobody can state which event is authoritative.
Define ownership before adding a tool. Product should own business semantics, engineering should own delivery guarantees and schema validation, and privacy reviewers should be able to trace each field from capture to deletion. For teams that need an explicit custom event layer in a Capacitor application, Capgo’s custom event tracking plugin guide is one implementation reference, not a substitute for deciding what each event means.
Architecture and Event Schemas for Mobile and Desktop Apps
A production pipeline has four distinct stages: instrumentation, durable buffering, transport, and ingestion. Keeping those boundaries clear prevents a temporary network failure from becoming an application failure.
In a Capacitor app, application code should call a small SDK wrapper rather than a vendor API directly. The wrapper adds common envelope fields such as session_id, app_version, platform, and consent state. That keeps call sites consistent and gives the team one place to redact fields, change sampling, or disable a broken tracker.
The queue should be persistent and append-only. An in-memory array disappears during a crash or process kill, exactly when diagnostic evidence is most valuable. Store events on disk, mark upload attempts separately, and make server ingestion idempotent through a stable event_id. Transport can flush on app resume, at a controlled interval, or when the queue reaches a size limit, with exponential backoff after failures.
A practical event envelope
| Field | Type | Required | Purpose |
|---|---|---|---|
event_id |
String | Yes | Deduplicates retries during ingestion |
event_type |
String | Yes | Routes and validates the event |
occurred_at |
Timestamp | Yes | Records client-side event time |
session_id |
String | Yes | Groups events into a user session without requiring a personal identifier |
app_version |
String | Yes | Identifies the installed application release |
bundle_version |
String | Optional | Identifies the active JavaScript or web bundle |
platform |
String | Yes | Distinguishes iOS, Android, macOS, Windows, or another runtime |
consent_state |
String | Yes | Applies collection policy before buffering and upload |
properties |
Object | Optional | Holds event-specific, validated fields |
network_state |
String | Optional | Adds context for delivery and offline analysis |
A checkout event might contain cart_item_count and payment_provider, but not an email address or unfiltered form text. The server should reject unknown fields or route them to quarantine. Silent acceptance of schema drift creates dashboards that look healthy while losing meaning.
Electron introduces another boundary. User actions normally occur in the renderer process, while system state, update status, filesystem access, and network coordination often belong in the main process. Use a narrow, validated IPC contract instead of allowing arbitrary renderer payloads to cross the boundary.
{
  "event_id": "evt_opaque_123",
  "event_type": "checkout_submitted",
  "occurred_at": "2026-09-18T02:14:00Z",
  "session_id": "sess_opaque_456",
  "app_version": "4.8.1",
  "bundle_version": "2026.09.18.2",
  "platform": "android",
  "consent_state": "functional",
  "properties": {
    "cart_item_count": 2,
    "payment_provider": "provider_a"
  },
  "network_state": "online"
}
An Electron renderer event can add process context without exposing user content:
{
  "event_id": "evt_opaque_789",
  "event_type": "window_action",
  "occurred_at": "2026-09-18T02:20:00Z",
  "session_id": "sess_opaque_456",
  "app_version": "4.8.1",
  "platform": "windows",
  "consent_state": "essential",
  "window_id": "window_opaque_12",
  "renderer_process_id": "renderer_opaque_34",
  "properties": {
    "action": "settings_opened"
  }
}
Capacitor plugin boundaries deserve explicit tests. A webview event may need bridging to native code for secure storage, device state, or native lifecycle signals. The Capgo app infrastructure guide provides relevant architectural context, but the durable rule is local ownership: capture UI intent in the renderer or webview, capture native lifecycle state at the native boundary, and correlate them through the shared envelope.
Sampling and Performance Trade-Offs
Sampling is a performance decision before it becomes a data science decision. Every event you drop can save serialization work, queue writes, battery, network transfer, and storage. Every event you drop can also remove evidence from an incident.
For a realistic mobile pipeline, serialized JSON events may be 1 to 4 KB, flush intervals may range from 5 to 60 seconds, and a typical session can generate dozens of actions. These figures come from the implementation brief, not a universal benchmark, so measure payload sizes and flush behavior on the devices your users operate.
Choose sampling by signal value
Capture business-critical events at full fidelity. Login, checkout submission, bundle activation, payment result, crash, and consent changes are difficult to reconstruct later and should remain available for operational truth.
High-volume signals such as render frames, scroll movement, verbose logs, and pointer motion are different. Client-side sampling is appropriate when the device cannot afford to serialize and queue every occurrence. A small headroom sample for UI telemetry can be useful, while errors and crashes should remain fully captured.
Server-side sampling works better when you want to preserve raw evidence temporarily but reduce query cost. Use a deterministic hash of session_id or an approved opaque user identifier so a session stays consistently included or excluded across related queries. Random sampling per event destroys sequence integrity.
Instrument the sampling decision itself. Store the rule version, inclusion result, and reason, then check whether battery state, platform, region, or consent state creates an unintended blind spot. Adaptive sampling can reduce low-value collection under thermal or battery pressure, but it must never reduce capture of failures or consent transitions.
Privacy and Compliance as a Design Constraint
Privacy belongs in the pipeline diagram, not in a launch checklist. The first architectural question is whether the SDK is allowed to create or buffer an event at all. If consent is required, the SDK must apply the gate before writing to disk, not after a queue has already retained the payload.
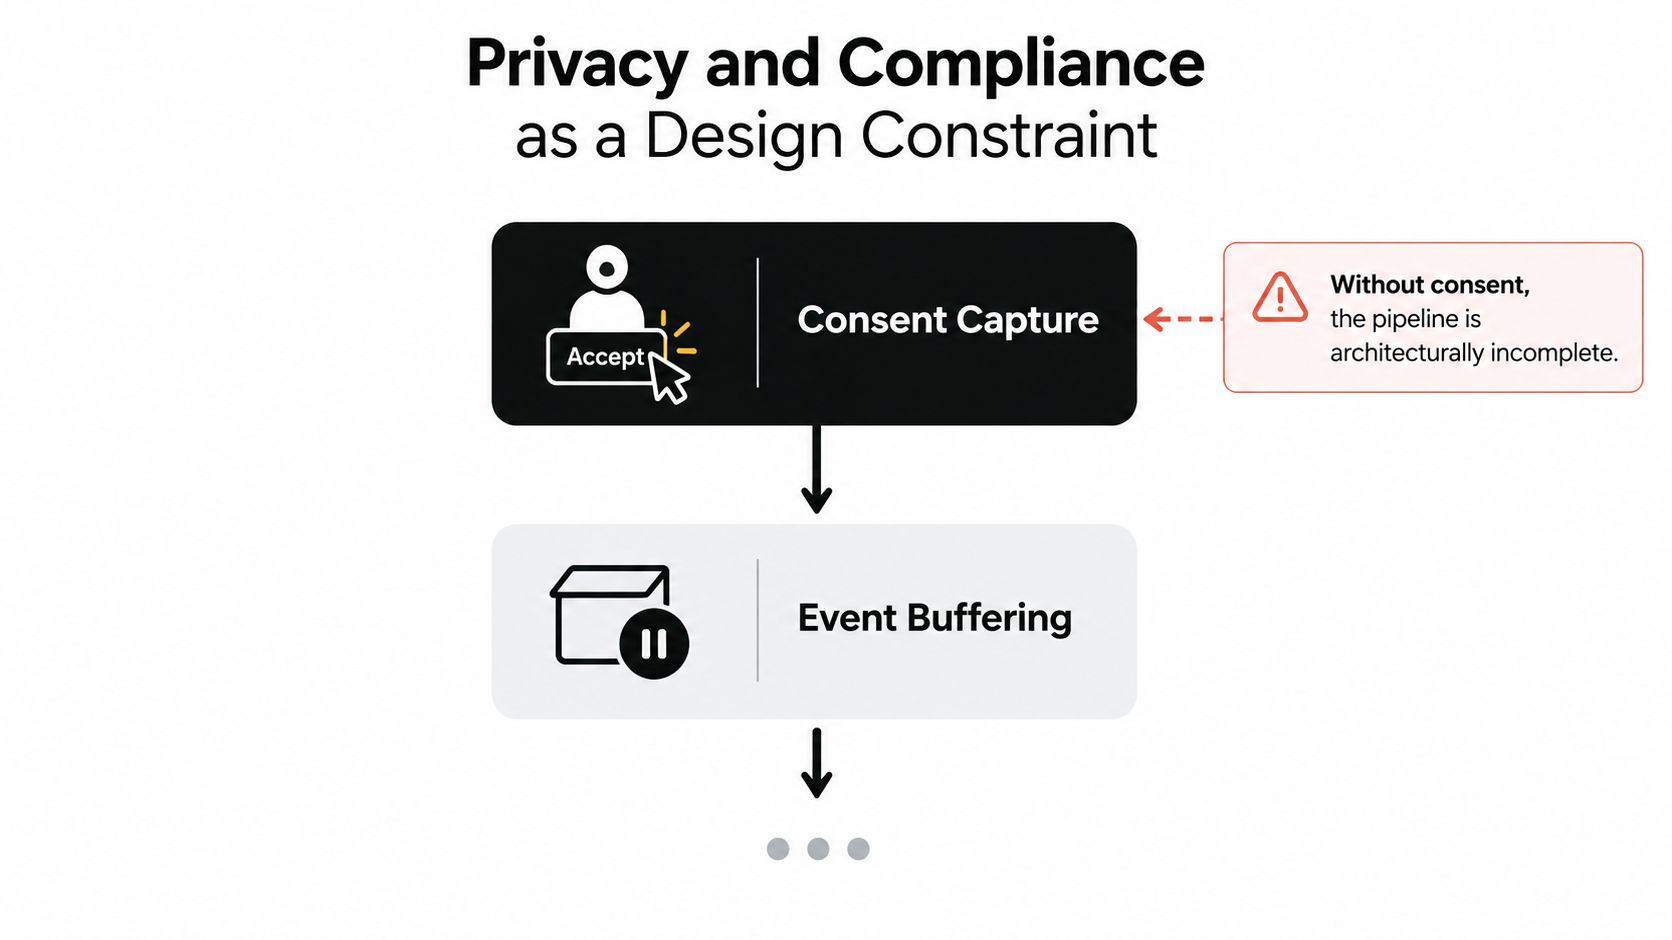
Use separate collection categories for essential reliability telemetry, functional product analytics, and optional marketing signals. Each category needs a clear policy, an SDK switch, and a server-side enforcement check. This approach also makes audits easier because reviewers can follow the decision from consent UI to buffer, transport, storage, and deletion.
Put controls at multiple boundaries
- At emission: Reject email addresses, phone numbers, payment details, and unbounded free text before an event enters the queue.
- At identity creation: Prefer opaque identifiers and rotate or scope them according to the product’s privacy model. Don’t treat a device identifier as harmless because it isn’t a name.
- At ingestion: Validate field types, permitted values, consent state, and regional routing metadata. Server validation is defense in depth, not permission to collect carelessly on the client.
- At storage: Keep raw events for a limited operational window, retain aggregates for longer only when justified, and apply the strictest retention rule to session replay because visual records carry greater exposure.
- At deletion: Make deletion requests propagate through hot storage, cold storage, derived tables, caches, and replay systems. A dashboard disappearing doesn’t prove the underlying record was removed.
Regional routing is also a systems concern. Determine the applicable region from a stable, documented signal, then send the event to an ingestion endpoint and storage location governed by the required policy. Teams reviewing the surrounding website and consent obligations can use this Coto & Waddington guide to website privacy as a practical legal resource, while still obtaining advice specific to their product and jurisdictions.
Platform rules reinforce the need for this separation. Industry reporting places global ATT opt-in around 27% to 38% in a 2026 benchmark, with the United States around 31%, Japan around 38%, Germany around 24%, and the United Kingdom around 26% (industry summary of Apple tracking behavior). Android’s Privacy Sandbox Attribution Reporting similarly moves advertising measurement toward aggregated reporting rather than cross-party identifiers, as described in this mobile analytics and privacy analysis. For implementation teams, Capacitor GDPR compliance guidance is useful only when translated into enforceable SDK and ingestion behavior.
Metrics, Dashboards, and Alerting That Actually Help
A tracking pipeline earns its place when it changes an engineering or product decision. Start with three views, adoption, quality, and pipeline health, then give each audience a dashboard that answers its own questions without redefining the underlying events.
Adoption metrics include weekly active usage, bundle adoption by channel, feature entry, and funnel completion. Quality metrics include crash-free sessions, failed requests, checkout errors, and client-side latency. Pipeline metrics include queue depth, upload success, ingestion latency, schema rejection, consent-gate decisions, and regional routing failures.
Metrics, signals, and alert patterns
| Metric Category | Example Metric | Healthy Threshold | Alert Pattern |
|---|---|---|---|
| Adoption | Active users on the intended bundle version | Defined by the release owner and rollout plan | Alert when adoption stalls beyond the planned observation window |
| Quality | Crash-free session rate | For example, above 99.5% over 30 minutes, a threshold specified in the operating brief | Page the mobile owner with platform, app version, and release channel attached |
| Funnel | Checkout step conversion | Compared with the approved baseline for the same cohort | Alert on a sustained, cohort-specific deviation rather than one noisy interval |
| Pipeline | P95 client ingest latency | Defined in the service objective for the ingestion path | Notify the data or platform owner when the objective is breached continuously |
| Data quality | Schema rejection rate | Near zero for released event versions | Open an incident when a new event type or app version causes a sudden rejection pattern |
The 99.5% crash-free session example and the P95 latency framing come from the operational requirements in this brief, not from a universal standard. Your team should record the owner, evaluation window, baseline, and runbook beside every alert. A threshold without a response path is dashboard decoration.
Engineering dashboards should show release version, platform, queue state, transport errors, ingestion latency, and schema failures. Product dashboards should show adoption, conversion, paths, and retention. Both views should use the same event contracts. The Capacitor performance monitoring guide offers a focused reference for connecting runtime signals to operational monitoring.
Best Practices and an Incident Recovery Checklist
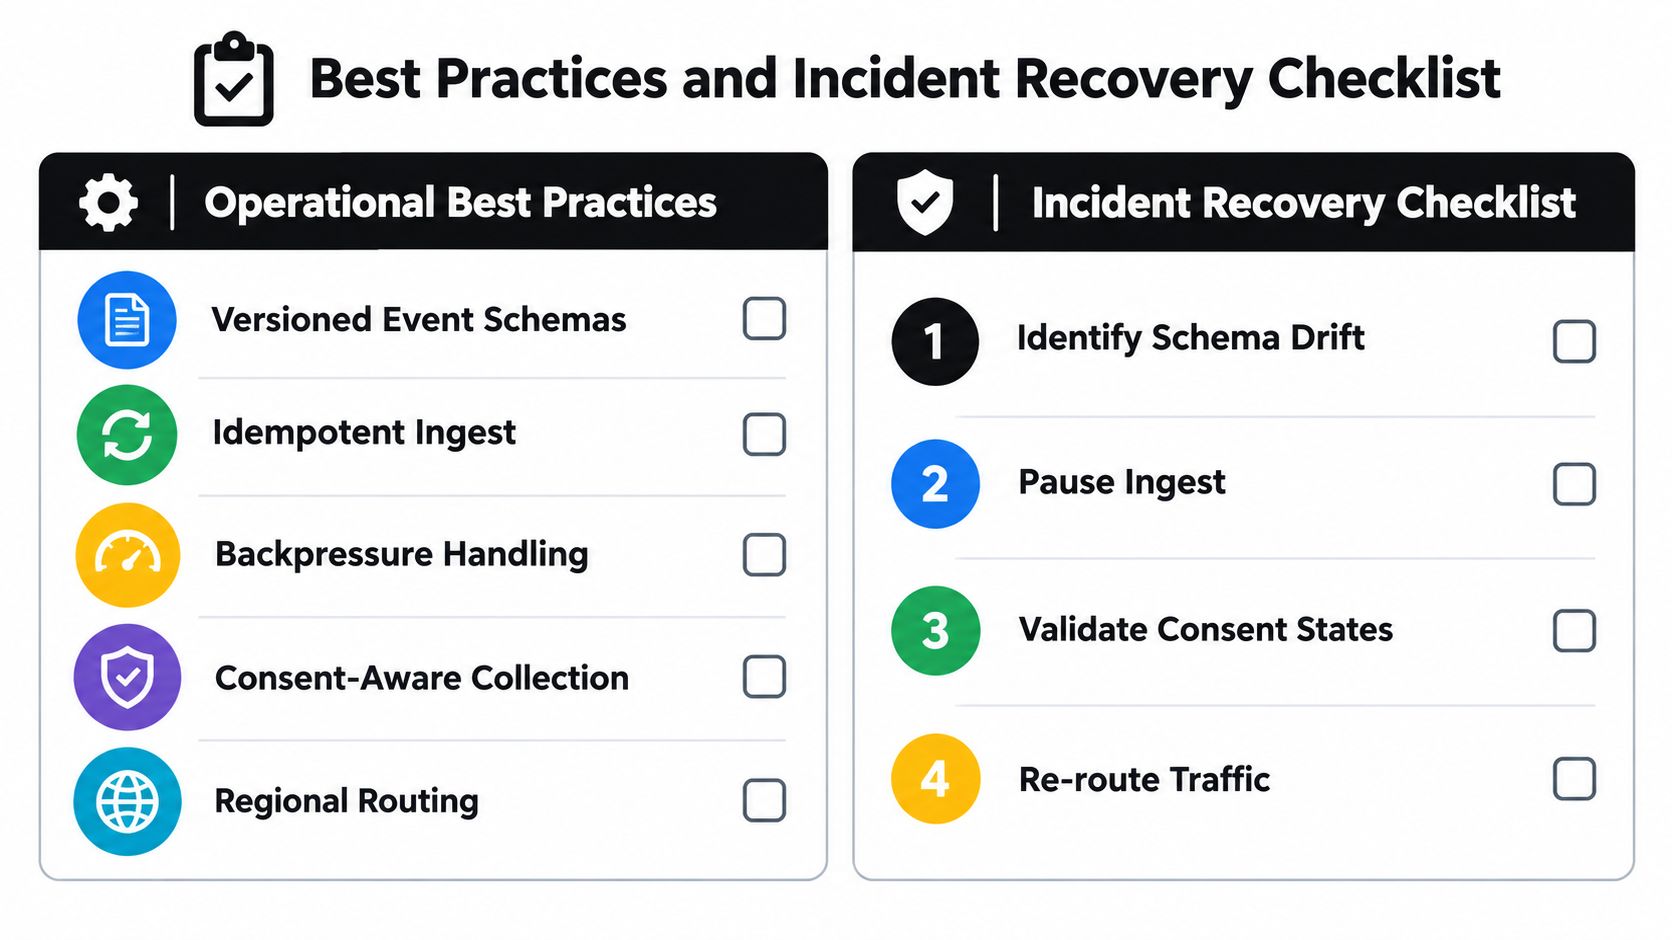
A dependable tracking system is mostly made of boring safeguards. Version every event contract, make ingestion idempotent, handle backpressure explicitly, enforce consent before buffering, and route data according to policy. These controls matter more than adding another dashboard because they determine whether the data remains trustworthy during a release or outage.
Operational checklist
- Versioned schemas: Publish event contracts with required fields, allowed properties, owners, and compatibility rules.
- Idempotent ingestion: Deduplicate by
event_id, especially when clients retry after timeouts or process restarts. - Backpressure handling: Cap queue growth, preserve priority for crashes and business-critical actions, and expose drop decisions as telemetry.
- Consent-aware collection: Apply consent before persistence and re-evaluate queued events when consent changes.
- Regional routing: Resolve region early, route deterministically, and test storage and deletion behavior in each supported location.
Incident recovery playbook
- Detect and classify. Compare the signal across app version, bundle version, platform, channel, and consent state. A sudden change isolated to one bundle may indicate schema drift or a broken SDK release, while a broad change may reflect real behavior or a policy update.
- Triage the pipeline. Check client queue depth, upload failures, ingestion latency, rejected fields, and duplicate rates. Pause or quarantine the affected event type if malformed payloads are polluting downstream systems.
- Mitigate safely. Disable the failing tracker through a remotely controlled feature flag when possible, or roll back the tracking bundle without changing unrelated product code. Don’t delete evidence before preserving the relevant queue and server records under the approved retention policy.
- Validate privacy state. Confirm that consent decisions, regional routing, redaction, and deletion paths still behave as designed. A tracking incident can be a privacy incident even when the product feature itself works.
- Recover and learn. Replay only validated, deduplicated events from durable buffers. Write a blameless postmortem that records the trigger, detection gap, affected schema, recovery action, and concrete pipeline or test changes.
App behavior tracking works when on-call engineers can trust the event contract, product teams can interpret the same facts, and privacy reviewers can follow every field through the system. If you ship Capacitor or Electron apps and need controlled JavaScript bundle delivery with release adoption, failure, device logs, channel targeting, and rollback visibility, visit Capgo to evaluate how its live-update platform can fit alongside your tracking pipeline. Start by mapping one critical release workflow, then connect its update state, runtime outcome, and recovery path before expanding coverage.



